Subtain Malik
AI/ML Solutions Architect · Netherlands
Production AI, from the GPU to the edge.
My models work at



Fig. 01 · Procedural silicon
Less memory. Less waiting.
More from every GPU.
88%
Less GPU memory
Peak VRAM on the same workload. A recurring crash, gone.
21.8×
Faster p95 latency
In the time one request took, 21 now finish.
23×
Faster LLM inference
Fine-tuned and quantized: 23 answers in the time of one.
$50K
Saved a year in cloud
One shared serving layer for 100K+ requests a day.
Systems I designed.
Greenhouses, feeds, cameras, satellites.
01
02
03
04
Gold medal. Published. On stage.
The parts outside production.
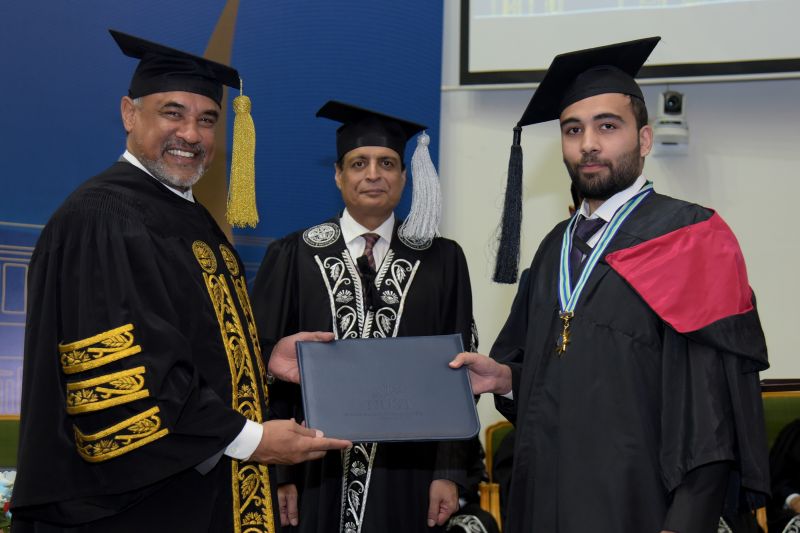
President's Gold Medal · CGPA 4.0 / 4.0
MS Computational Science & Engineering, NUST
Top of the programme, 2018–2021. See the post ›
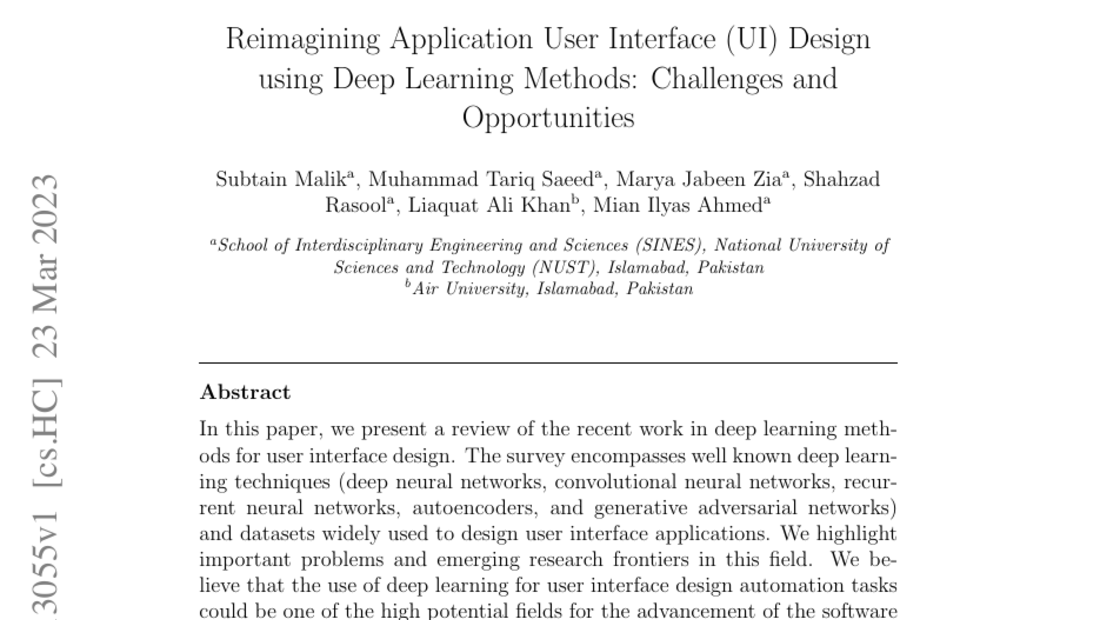
Research paper · arXiv, 2023
Reimagining Application UI Design using Deep Learning
Challenges and opportunities. First author. Read on arXiv ›
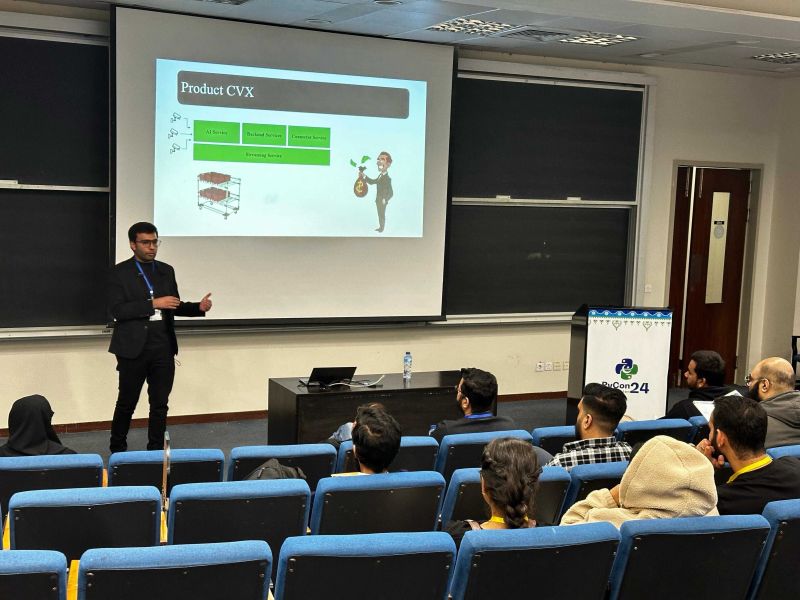
PyCon Pakistan · 2024
Python and the Multiverse of Cameras
A tale of synchronization and streams. Watch the talk ›